SadTalker Output Benchmark Lab
Compare recorded output videos, inspect their inputs and settings, and check the time each render took.
100 verified outputs · 14 settings combinations · 6 image categories · English narration · RTX 4090 · Per-run dates in the evidence
Repeat trials are separate recorded outputs with the same settings, not different input cases. Warm-ups and edited comparison montages are excluded. Videos load when you choose Play output. Compressed previews keep browsing light; raw outputs are available in each entry.
100 matching outputs of 100 · Page 1 of 17
Abraham Lincoln, 1863
Input variants · Distinct input/settings run
crop · 256 · Still OFF · GFPGAN OFF
Synthetic animation · Male narration · 4-second narration excerpt
- Execution time
- 20.742 s
- GPU
- RTX 4090
Input, settings and artifact notes
Run: new-01-lincoln · 2026-10-13
4-second excerpt of existing website narration. Synthetic speech animation paired with a website narration excerpt; not a historical voice recording.
Library of Congress, Alexander Gardner, 1863; original scan, unchanged.
Source portrait · Narration audio
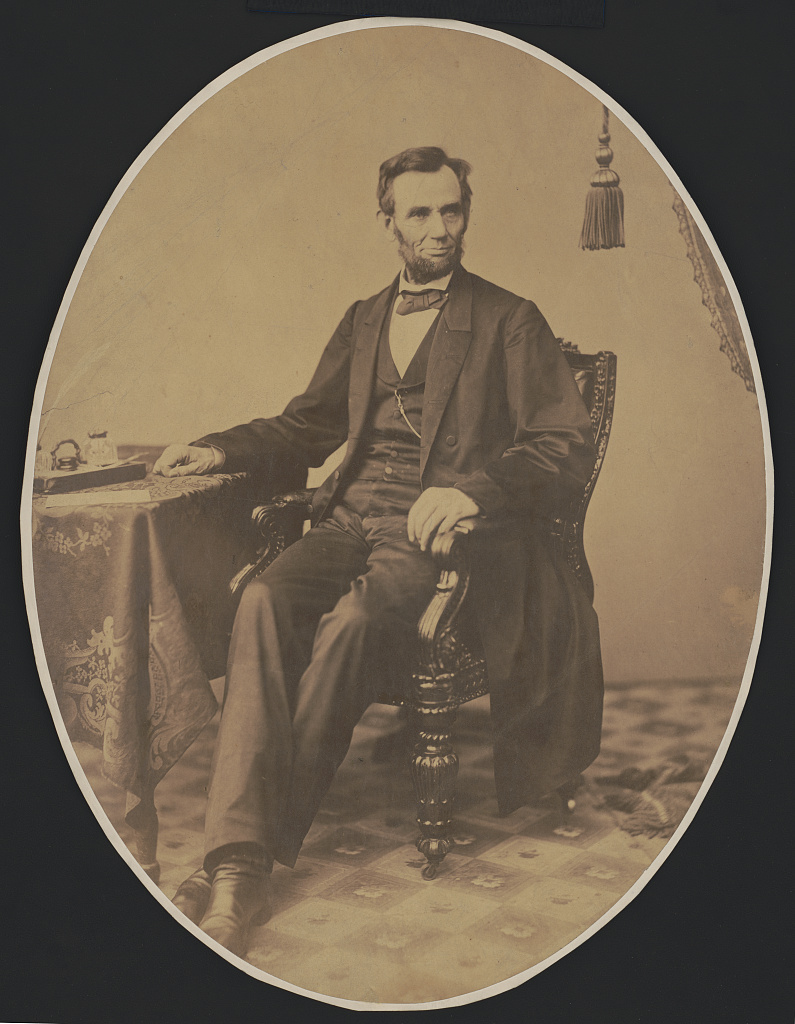
The sampled face crop retains the scan’s sepia tone and soft texture. Teeth and the open-mouth edge appear less uniform than the closed mouth in the original scan.
Individual sampled-frame observation; not a temporal-artifact or lip-sync score.
Batch 2 · Expression 1 · Pose 0
Output SHA-256
5cc9930560b424fe91c4c652db012897e7d3bec9e1a0d68d798d29337d1a9e1f
Harriet Tubman, 1868 or 1869
Input variants · Distinct input/settings run
crop · 256 · Still OFF · GFPGAN OFF
Synthetic animation · American conversational narration · 4-second narration excerpt
- Execution time
- 20.619 s
- GPU
- RTX 4090
Input, settings and artifact notes
Run: new-01-tubman · 2026-10-13
4-second excerpt of existing website narration. Synthetic speech animation paired with a website narration excerpt; not a historical voice recording.
Library of Congress, Benjamin F. Powelson, 1868 or 1869; original scan, unchanged.
Source portrait · Narration audio
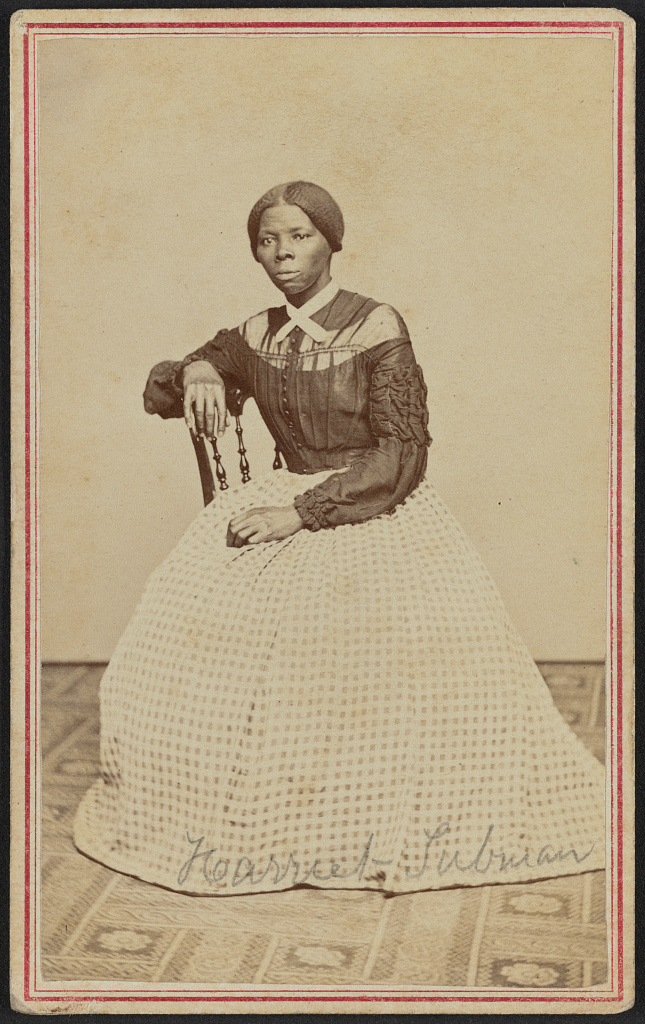
The sampled crop enlarges the archival face and shows an open mouth. Facial edges remain soft; the original card border and seated body are outside this crop.
Individual sampled-frame observation; not a temporal-artifact or lip-sync score.
Batch 2 · Expression 1 · Pose 0
Output SHA-256
82a69c099c303e8724f668b2f33628c837027e3bbb07aac44faca8ab070b24a6
Fictional AI presenter
Input variants · Distinct input/settings run
crop · 256 · Still OFF · GFPGAN OFF
Synthetic animation · Young-creator narration · 4-second narration excerpt
- Execution time
- 21.377 s
- GPU
- RTX 4090
Input, settings and artifact notes
Run: new-01-ai-woman · 2026-10-13
4-second excerpt of existing website narration; no new speech synthesized for this run.
Generated for this benchmark with the built-in image generation tool on 13 October 2026.
Source portrait · Narration audio
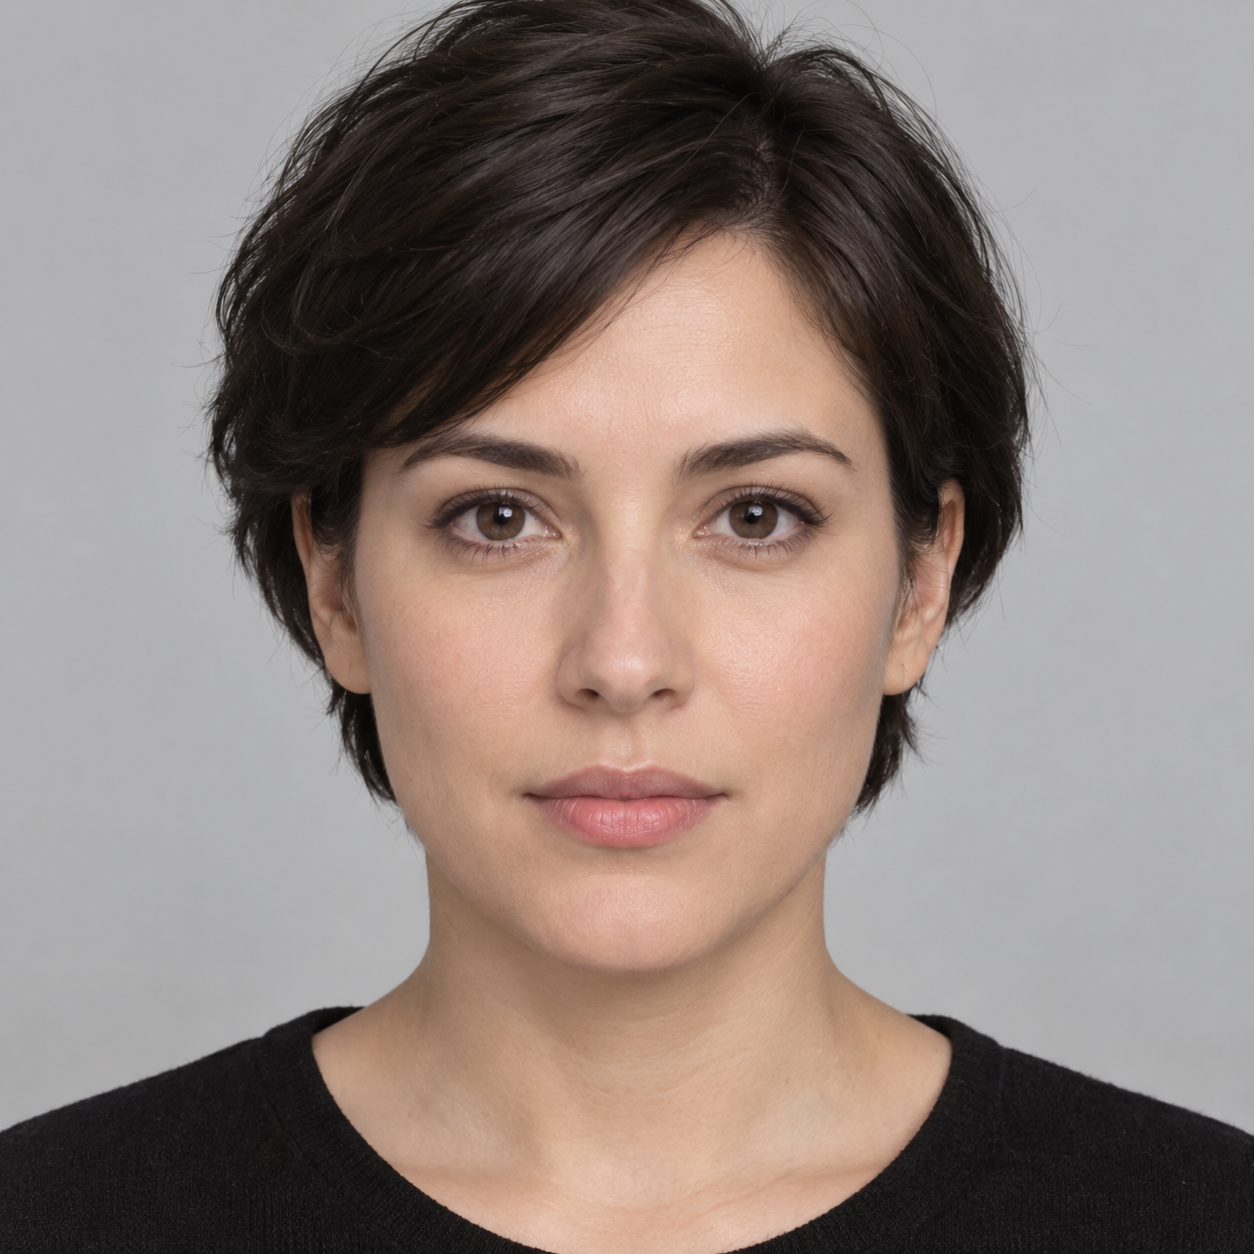
The sampled frame shows the fictional presenter with visible teeth and a plain gray background. Compare the mouth and tooth detail with the input; a sharp still frame does not establish lip-sync accuracy.
Individual sampled-frame observation; not a temporal-artifact or lip-sync score.
Batch 2 · Expression 1 · Pose 0
Output SHA-256
9ad21579afca2479fb587995fe359fc84b74e0ca347eba6adc73e0891bf12eb1
Corporate presenter
Input variants · Distinct input/settings run
crop · 256 · Still OFF · GFPGAN OFF
Synthetic animation · Corporate narration · 4-second narration excerpt
- Execution time
- 21.023 s
- GPU
- RTX 4090
Input, settings and artifact notes
Run: new-01-corporate · 2026-10-13
4-second excerpt of existing website narration; no new speech synthesized for this run.
Existing website demo source; unchanged.
Source portrait · Narration audio
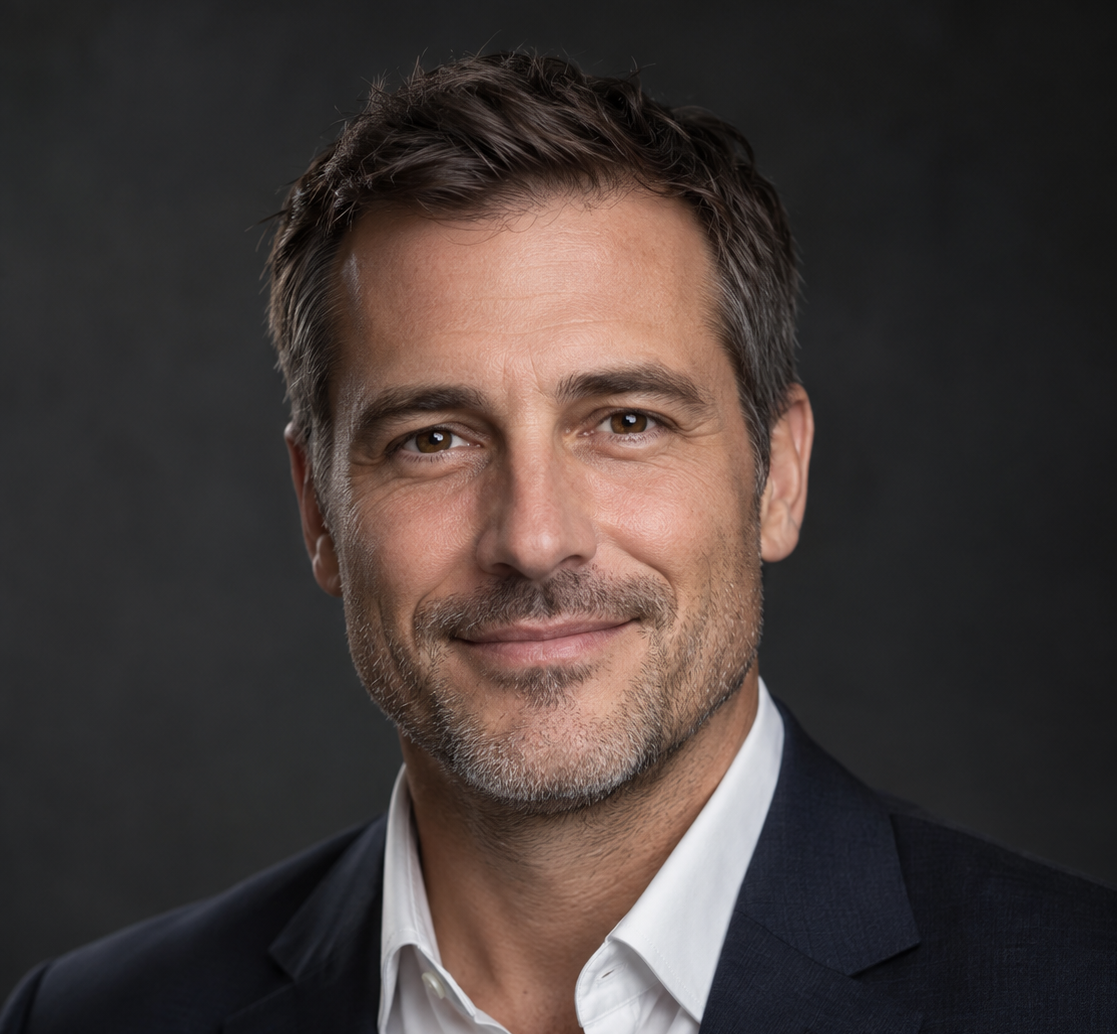
The sampled frame retains the dark studio background and facial hair. The mouth and eye opening vary between runs, and beard detail appears soft in the smaller base renders.
Individual sampled-frame observation; not a temporal-artifact or lip-sync score.
Batch 2 · Expression 1 · Pose 0
Output SHA-256
6dc929e35c32a5806f3f7cef31b72c7bfc7a823024b21d1d40f4fe45f9abf427
Female presenter
Input variants · Distinct input/settings run
crop · 256 · Still OFF · GFPGAN OFF
Synthetic animation · Male narration · 4-second narration excerpt
- Execution time
- 21.013 s
- GPU
- RTX 4090
Input, settings and artifact notes
Run: new-01-female · 2026-10-13
4-second excerpt of existing website narration; no new speech synthesized for this run.
Existing website demo source; unchanged.
Source portrait · Narration audio
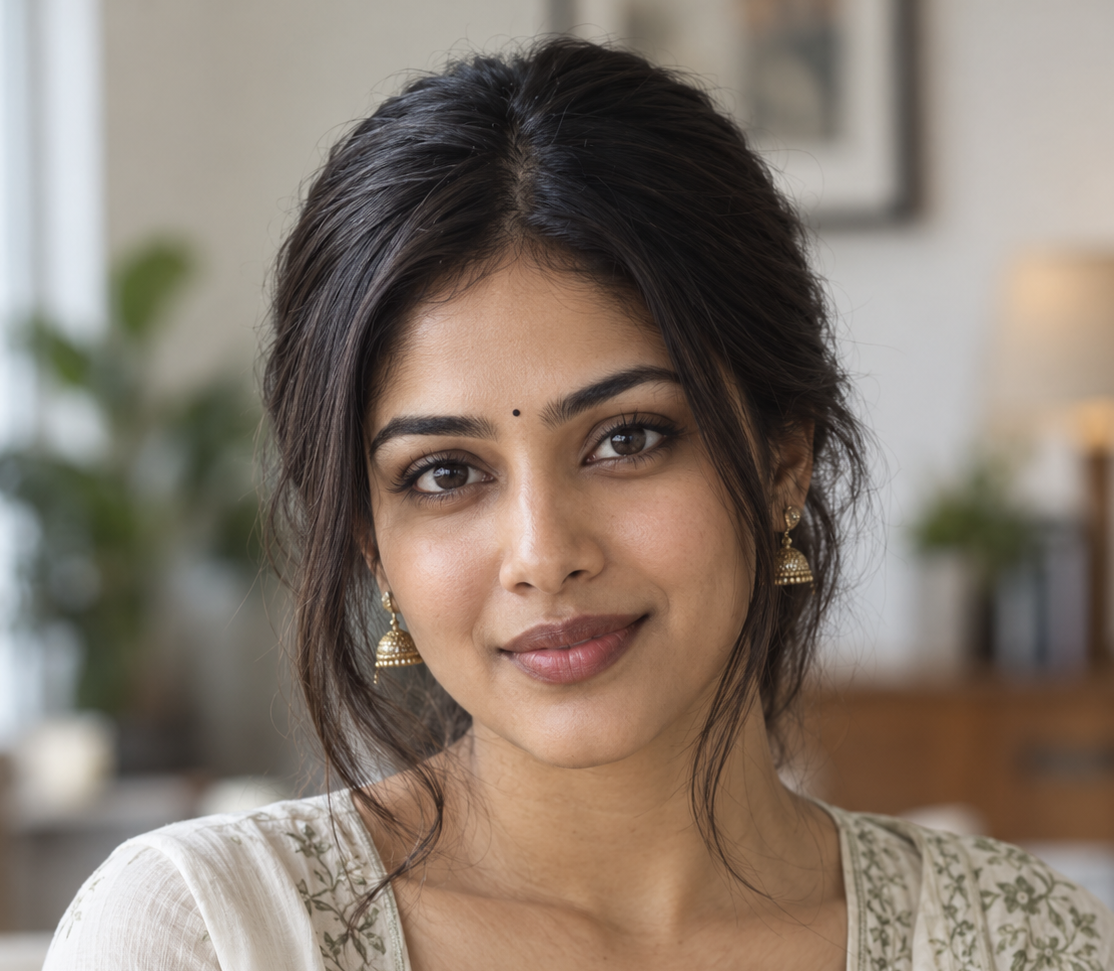
The sampled crop retains the portrait’s hair and face markings. Teeth become visible during speech; inspect the mouth edge and nearby cheek texture in the moving output.
Individual sampled-frame observation; not a temporal-artifact or lip-sync score.
Batch 2 · Expression 1 · Pose 0
Output SHA-256
23737ccfd2bad2e259ffcd7cdcfe4e8fee6a0fbfefd42107232bc567c5ea35fc
American narrator portrait
Input variants · Distinct input/settings run
crop · 256 · Still OFF · GFPGAN OFF
Synthetic animation · Female instruction · 4-second narration excerpt
- Execution time
- 21.077 s
- GPU
- RTX 4090
Input, settings and artifact notes
Run: new-01-american · 2026-10-13
4-second excerpt of existing website narration; no new speech synthesized for this run.
Existing website demo source; unchanged.
Source portrait · Narration audio
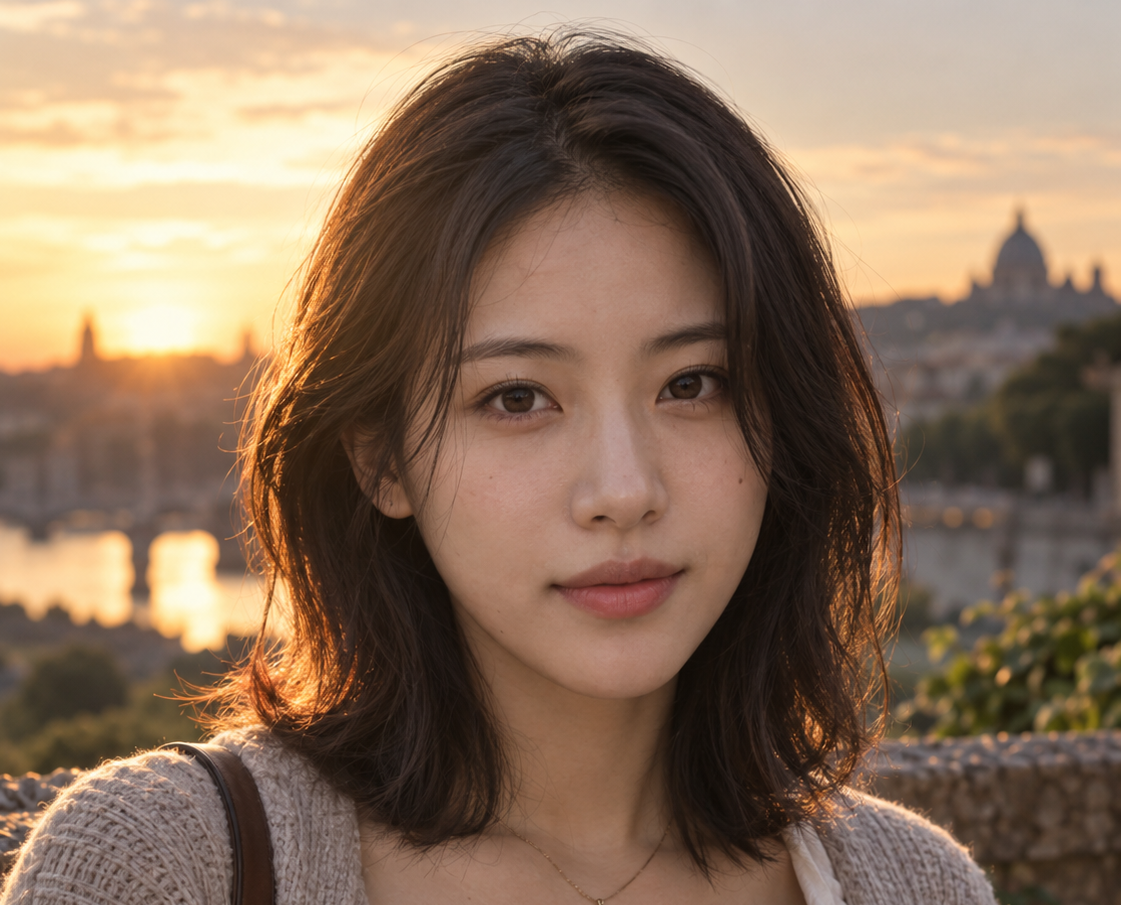
The sampled frame retains warm background lighting. Mouth shape and visible teeth differ from the closed-mouth source; compare facial detail at the intended display size.
Individual sampled-frame observation; not a temporal-artifact or lip-sync score.
Batch 2 · Expression 1 · Pose 0
Output SHA-256
7e238d5001fb9e4425acf498596b4147331423f328a6ad7f9f915a523d48d366
How these entries are verified
Each video’s SHA-256 matches its source benchmark record. The raw ComfyUI history records a completed execution, and its execution_start to execution_success interval matches the displayed time. Settings come from that run’s prompt. The portrait and audio hashes match the inputs in the benchmark records.
The input-variant runs use four-second excerpts of existing website narration. The original settings comparisons use the full narration clip. Compare render times only when input, duration and runtime match.
Execution time includes input loading, worker/model startup, inference and export, and excludes queue wait and initial installation. The card shows a single run, not a median. GPU, software versions and measurement methods are recorded in the linked source JSON. Export dimensions can differ from the 256 or 512 base renderer size.
Notes state whether they come from a per-run frame review or series-level observations from the original comparisons. They guide inspection of framing, motion and restored detail; they are not individual quality scores. Independent outputs can differ in blinking and expression, so a visual difference does not necessarily come from the changed setting.