SadTalker Live Demo Studio
Experience interactive NVIDIA RTX demos of SadTalker in action. See how SadTalker transforms a single static photo and an audio voice track into a realistic, lip-synchronized talking avatar rendered on NVIDIA RTX GPUs (RTX 4090 & 3090) with GFPGAN face restoration.
Professional Female Presenter & Course Instructor
Clean studio lighting portrait paired with clear, professional instructional narration. Demonstrates steady eye contact, natural blinking timing, and anchored shoulders via --still mode.
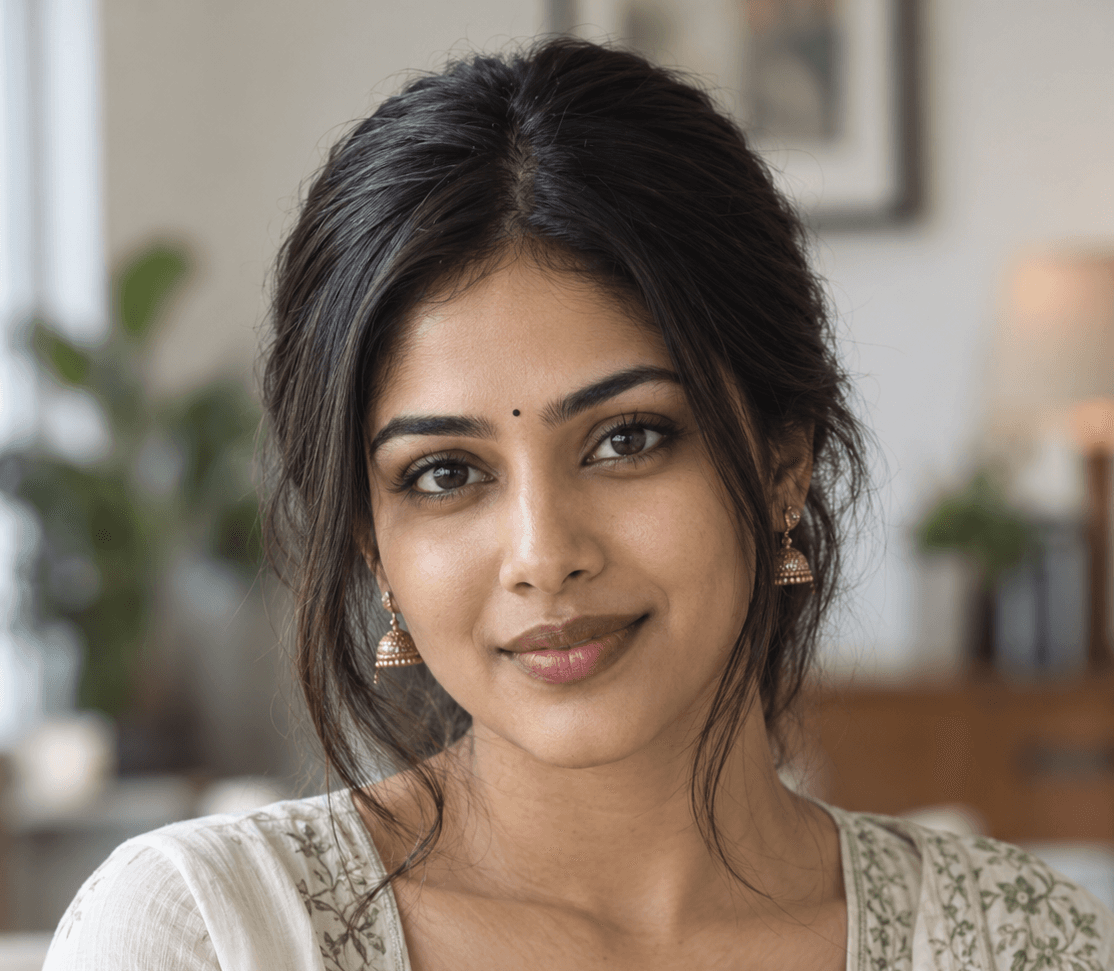
Portrait Preprocessing:
• Mode: --preprocess crop
• Face Crop: Auto 3DMM alignment
✓ Unmodified single frame input
Female Studio Narration (Clean English)
python inference.py --source_image ./sadtalker-female-portrait-source.png --driven_audio ./sadtalker-female-narration-audio.wav --result_dir ./results --size 512 --still --preprocess crop --enhancer gfpganExplore All 5 Audio-to-Video Demonstrations
Compare how SadTalker adapts to different voices, head poses, speech tempos, and character demographics.
Emma — Professional Female Presenter & Course Instructor
Clean studio lighting portrait paired with clear, professional instructional narration. Demonstrates steady eye contact, natural blinking timing, and anchored shoulders via --still mode.
Sarah — American Accent Explainer Video Presenter
Conversational American English speech with natural dynamic inflections. Demonstrates fluid jaw motion, subtle cheek muscle movement, and zero visual stuttering.
Alex — Male Digital Avatar & Tech Reviewer
Synthetic 3D character portrait animated with clear male audio. Shows how SadTalker seamlessly animates Midjourney, Stable Diffusion, or 3D digital human avatars.
Marcus — Fast Paced Urban Social Media Creator
High-tempo speech bursts with rapid rhythmic syllables. Tests SadTalker’s latency and demonstrates that speech timing stays locked without drifting.
David — Executive Briefing & Corporate Spokesperson
Deep, resonant male speech paired with a mature corporate portrait. Shows GFPGAN preserving facial creases, natural skin texture, and dignified composure.
SadTalker Settings Starting Points
This finder uses the same rules as the Settings Finder. It suggests starting points for your inputs. See the Best Settings master guide for captured settings evidence and limitations.
Choose your photo type, audio recording qualities, and production goal. The finder suggests settings to try; it cannot predict or prevent distortion, jitter or GPU memory errors. Inspect a short render first.
Target Parameters for Your Use Case
python inference.py --source_image "input.png" --driven_audio "input.wav" --result_dir "results" --preprocess crop --size 512 --batch_size 2 --expression_scale 1.0 --pose_style 0Want to Generate With Your Own Photo Right Now?
You don't need an expensive local GPU to generate custom SadTalker videos. Use these official free cloud options:
Hugging Face Spaces Demo
The official interactive Gradio web application. Upload your image, record your voice directly with your microphone, and render videos online without installing any software.
- ✓ 100% Free browser GUI — no programming required
- ✓ Supports 256px and 512px models + GFPGAN
- ✓ Instant drag-and-drop upload
Google Colab 1-Click Notebook
Run full SadTalker inference on a free cloud NVIDIA T4 GPU. Perfect for long videos, batch avatar rendering, and testing custom checkpoint weights.
- ✓ Cloud GPU without local hardware wear
- ✓ Full GFPGAN high-resolution post-processing
- ✓ Step-by-step pre-configured cells
Planning Local Setup on Your Own PC?
Our captured GPU comparisons use NVIDIA CUDA. Memory requirements vary with the input, software and settings; these card capacities are not guaranteed minimum requirements.
Frequently Asked Questions
Can I test SadTalker for free without coding?
Yes! The official Hugging Face Space offers a zero-code web interface where you can drag and drop your photo and voice track. You can also run the 1-click Google Colab notebook completely in the cloud.
What does the GFPGAN enhancer do?
SadTalker’s 3DMM renderer generates facial movement at 256×256 or 512×512. When the --enhancer gfpgan flag is included, each output frame is passed through optional GFPGAN restoration. It may sharpen eyes and facial hair or smooth skin, but it can also generate altered texture and teeth. Compare the output against the original likeness.
Why should I use the --still flag?
By default, SadTalker simulates natural head tilting and breathing motions. For educational courses, corporate explainers, or news broadcasts, excessive swaying can distract viewers. The --still flag locks the torso and neck in place so all motion is dedicated to expressive lip-sync and eye movement.
How long does it take to generate a video?
Generation times depend primarily on your GPU and whether GFPGAN face enhancement is enabled. In our verified hardware benchmarks for an 11.24-second audio clip (281 frames at 512px with GFPGAN):
- NVIDIA RTX 4090 (24GB): 40.490 seconds (10.60 it/s enhancer speed)
- NVIDIA RTX 3090 (24GB): 130.135 seconds (2m 10s) (2.75 it/s enhancer speed)
- NVIDIA RTX 3060 (12GB): ~195 seconds (~3m 15s) (~1.9 it/s enhancer speed)
- Fast 256px Mode (No enhancer): Under 15s on RTX 4090; ~42s on RTX 3060.